When Is a Glass Full? An Experiment on Semantic Precision in Large Language Models
Abstract
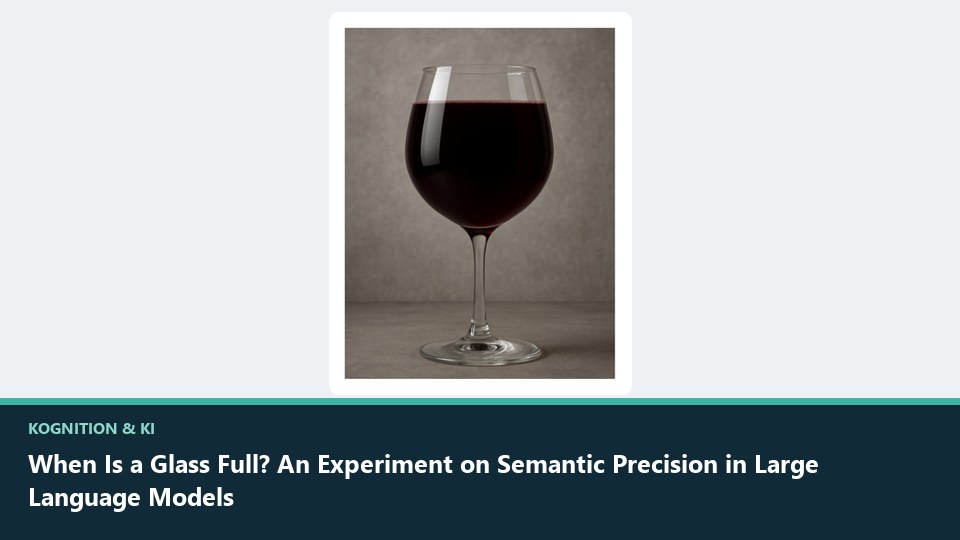
This study explores how a large language model (LLM) interprets the concept of 'full' when generating visual content. Although the instruction appears unambiguous to a human observer, the model initially applied a colloquial interpretation rather than an exact physical one. Through the introduction of explicit reference images and iterative corrective feedback, the model’s representation of fullness converged toward a technically precise definition. The experiment demonstrates that semantic accuracy in LLM systems is not static but can be actively shaped through interaction, grounding, and constraint reinforcement. This experiment relates to established discussions on semantic grounding and interpretability in LLM systems , 1990; . ,2021.
Context
Qualitative Fallstudie zur Interpretation des Begriffs „voll“ bei KI-generierten Bildern. Referenzbilder und schrittweise Rückmeldungen dienen dazu, die visuelle Darstellung an einer expliziten physikalischen Bedeutung auszurichten. Einzelfallbeobachtungen sind von allgemeinen Aussagen über Sprachmodelle zu unterscheiden.